Introduction
In a previous article, while dissecting the P104-100 mining accelerators, I briefly mentioned that despite its age, the Pascal architecture still handles image generation quite well. Frankly, one could stop there and accept that the old GTX 1070/1080/1080Ti, P104-100, or P102-100 cards are simply nearing the end of their lives. However, there's always a significant "but." Watching these cards struggle with stable-diffusion.cpp on modern, demanding models like Krea 2 or Z-Image, I couldn't shake the feeling that the software was only utilizing a third of the silicon's true potential.
Let's take a quick technical dive to ensure we're all on the same page. Why do Pascal family graphics cards (the GTX 1000 series and their "headless" mining counterparts P104/P102) struggle so much with modern neural networks? It all comes down to two strict hardware limitations:
Complete absence of Tensor Cores. These only appeared in the subsequent generations (Volta/Turing).
Drastically cut-down FP16 unit. On consumer Pascal-based GPUs (CUDA capability level SM 6.1 — GP102, GP104, GP106, and GP107 chips), half-precision performance (
FP16/half2) is artificially throttled by a whopping 64 times compared to standardFP32(the so-called 1:64 penalty).
This means any modern code that gets a twofold acceleration by switching from FP32 to FP16 on, say, an RTX 2060 Super or RTX 3090, either doesn't work at all on GTX 1000 cards or turns the graphics card into a slideshow.
But what else do we know about Pascal-architecture GPUs (except for maybe the office-grade GT 1030 with its GP108 chip)? That's right – it was in the SM 6.1 chips that NVIDIA engineers added a fascinating, yet often overlooked, hardware instruction: __dp4a (Dot Product of 4x 8-bit Integers and Accumulate). To put it simply: instead of computing heavy 32-bit floating-point numbers one at a time per clock cycle, the graphics card simultaneously takes four 8-bit integers (INT8), multiplies them with another quartet, and accumulates the result into a 32-bit accumulator. And it does all of this in a single clock cycle!
Let's look at the raw numbers using the popular GTX 1070 as an example:
In classic
FP32mode, its ceiling is around 6.5 TFLOPS.However, in
INT8 __dp4amode, the theoretical peak jumps to around ~26 TOPS. This means the silicon is physically capable of churning out four times more mathematical operations in the same amount of time!
The idea, therefore, presented itself: what if we could force stable-diffusion.cpp to compute demanding diffusion models (Anima, Krea 2, Z-Image) using the fast, native INT8 __dp4a mode, without sacrificing image quality or exceeding the 8 GB VRAM limit?
How it all happened
Let me be upfront: I'm a hardware guy and an overclocker. While I thoroughly understand chip architecture, memory operation, and pipeline logic, writing low-level matrix kernels from scratch in C++/CUDA with intrinsics, shared memory, and warp reductions is simply beyond my capabilities. So, this project came to life through a rather unique collaboration.
This whole saga began with Gemini 3.8 Flash, but honestly, we quickly hit a wall with it. The "old one" would occasionally make rookie coding mistakes, stubbornly argue with my engineering hypotheses, and generally push the narrative that Pascal had already been squeezed dry. But my gut feeling told me otherwise: the GPUs were falling back to FP32 and not flexing their full potential.
The real breakthrough came when we switched to the new Gemini 4 Hydrogen (which I'll just call "Hydra" from now on, because after dozens of hours spent coding together, it feels like family). That's when the work moved to a completely different level. Hydra behaved like a seasoned systems engineer: it took my architectural ideas without unnecessary arguments, translated them into clean CUDA code, immediately tested them on live hardware, and only in those extremely rare cases where my concept objectively failed at the mathematical or compiler level, would it logically suggest an alternative approach.
Was it easy? Of course not! Our code review revealed that simply "bolting on" __dp4a to stable-diffusion.cpp wasn't going to work. Parts of it were already there, and the legacy from our initial 3.8 Flash attempts held many surprises. So, let's dive into where the slowdowns were lurking and how we managed to almost double the speed of good old Pascal.
A few details
Hydra and I made a crucial discovery during our post-mortem analysis: the stock ggml-cuda backend already supports __dp4a on Pascal cards! What's more, it does this inside its standard quantized mmq (matrix multiplication quantized) kernel.
You'd think, "great, our work is done, it's already written," right? Not quite. The problem with the stock mmq is that it operates on small 64×64 tiles and constantly wastes chip resources unpacking complex quantization blocks directly during matrix multiplication. As a result, on a GTX 1070, the stock kernel only delivered a paltry ~7.8 TOPS out of a theoretical 26 TOPS peak performance. This means over two-thirds of the GPU's computational potential sat idle due to suboptimal memory and register usage. That's why our initial naive attempts to "just drop in our own __dp4a" without completely redoing the tiling and caching hit the wall of the stock code, or even performed worse.
Furthermore, after updating the stable-diffusion.cpp codebase to the latest master (commit b9d7176, ggml submodule d803c238) and Hydra conducted a full audit of the older code—which we started writing back with Gemini 3.8 Flash—three critical issues surfaced:
Dead architecture check. In the old code, the GPU generation check was
cc == 61. Sounds logical for SM 6.1, right? Wrong: insideggml-cuda, architecture versions are multiplied by one hundred, so for Pascal, the constant610(GGML_CUDA_CC_DP4A) is used. This simple oversight meant our custom path never activated on actual GTX 1000 cards.Bit unpacking and dimensionality errors. The initial
Q4_KandQ3_Kdequantization functions had bit-shifting bugs, theQ8_0format was completely missing, and crucially, the code didn't check for higher tensor dimensions (ne2 / ne3) or their memory contiguity (contiguous). Consequently, when attempting to process multi-dimensional batches, the kernel could read garbage data from memory.Missing build macro. The CMake build system simply failed to pass the
SD_USE_CUDAmacro to the finalsd-clibinaries (and later, tosd-server, as we found out). This meant you could specify the--dp4aflag in the console all you wanted, but the executable itself had no idea it was allowed to call our backend's CUDA functions.
To definitively address compatibility and ensure a clean experiment, we compiled a single, unified binary (sd-cli_DP4a.exe and sd-server_DP4a.exe via portable-msvc + CUDA 12.9 + Ninja). The logic is straightforward: by default, it runs as a 100% clean stock version, but adding the --dp4a flag (or setting the SD_CUDA_DP4A=1 environment variable) activates our accelerated pipeline. For the server version, sd-server_DP4a.exe, we enabled --dp4a by default to seamlessly integrate the acceleration into our CoT Studio web shell without any extra hassle.
How we tested
Anyone who's followed my work knows I can't stand 'canned' or manipulated benchmarks. I'm talking about tests where, say, a browser randomly unloads in one run, or the model has to hit slow system RAM due to driver swap in another. To avoid any discrepancies on our test bench, equipped with GTX 1070 8 GB (CUDA_VISIBLE_DEVICES=0), we established a strict testing protocol, consistent for both stock configurations and --dp4a:
Sequential module offloading (
--offload-to-cpu --mmap) and the text encoder on the CPU (--backend te=cpu). Why this setup? When you're generating an image on an 8 GB graphics card, keeping both a hefty text encoder (like Qwen 3 VL or T5) and the diffusion model in memory at the same time is a guaranteed VRAM overflow. With our setup, the CPU calmly handles the text (the input prompt). Then, during the actual sampling (Stage 2), the GTX 1070's VRAM holds only the diffusion model.Mandatory FlashAttention (
--diffusion-fa) and VAE tiling (--vae-tiling --vae-tile-size 512x512). Here's an interesting story that highlights the difference in approaches between the two models. Early in the Gemini 3.8 Flash project, it aggressively promoted the idea of small VAE tiling64x64(arguing it was safer for VRAM) and stubbornly pushed back when I advocated for512x512. However, when we transitioned to Hydra, it immediately tested my preferred tile size512x512— and it turned out I was completely right: this size perfectly fits into VRAM, provides adequate decoding speed, and doesn't introduce unwanted seams into the image.Fixed
--seed 42. This forms the basis for direct visual comparison. We verified each test generation down to the pixel and detail, ensuring that the shift to 8-bit integer math didn't turn the image into a blurry mess.Separate time measurement. We separately recorded the pure runtime of the sampler itself (
Stage 2, step speed ins/it) and the total generation time, from launch to saving the PNG to disk.
Architectural evolution: 5 steps to the final result
After clearing out old bugs and establishing a stable test bench, the primary engineering challenge emerged: how to design a computational pipeline that could extract the maximum 26 TOPS from the GTX 1070 and P102 without running into VRAM constraints? We arrived at the final architecture after five iterations.
Step 1. Large-tile W8A8 pipeline 128x128 __dp4a GEMM (dp4a_gemm.cu)
Why did the stock mmq kernel so underutilize the chip? It's because it operates with small 64x64 tiles and attempts to unpack complex ggml quantization formats (where bits are mixed with scales within blocks) directly on the fly during matrix multiplication.
We took a different approach, implementing a full-fledged W8A8 matrix pipeline (where both model weights and activations are converted to a pure 8-bit int8):
Pre-packing of weights. The model's quantized layers are unpacked beforehand into a maximally simple, 'flat'
int8array with a separate row scaling coefficient (scale_B[N]). No bit shifts during the multiplication itself!Fast, on-the-fly activation quantization. Input activations (which are
FP32) are instantly quantized toint8before multiplication, complete with their own scale (scale_A[M]), using widefloat4vector loads (kernel_quant_row_f32_to_i8_vec4).Massive
128×128kernel. The matrix multiplication kernel itself (kernel_w8a8_dp4a_128x128) computes a large128×128tile. To prevent kernel starvation, data is loaded from the chip's internal Shared Memory via wide 128-bitLDS.128transactions (typeint4— 16int8numbers per clock cycle) with register prefetching. After__dp4arapidly multiplies integers into anint32accumulator, the result is simply multiplied byscale_A * scale_Band returned as a trueFP32.
What did this achieve in practice? The very first benchmark on a light test model, anima-Q4_K (512×768, 20 steps), showed that sampling time on a GTX 1070 dropped from a stock 49.24 s (2.41 s/it) to 37.15 s (1.78 s/it). That's a 32.5% speed increase on the first try! But this was just a warm-up.
Step 2. Native INT8 __dp4a FlashAttention (fattn_dp4a.cuh)
After optimizing standard matrix multiplication (MUL_MAT) and enabling the internal profiler (SD_CUDA_PROF=1), the situation shifted: the primary bottleneck became the attention block — FLASH_ATTN_EXT — consuming up to 20–25% of each generation step's time. This makes sense: the stock ggml-cuda for Pascal architecture simply lacks a fast, specialized FlashAttention kernel, forcing the GPU to process heavy attention matrices through slow FP32 paths.
Hydra and I decided to tackle this bottleneck, writing our own kernel_flash_attn_dp4a<D> kernel (initially for the standard attention head dimension of head_dim = 128, later adding support for head_dim = 64 with memory boundary protection for warp threads lane >= 16):
Matrix tiles for
Q,K,P, andVare quantized toINT8directly on the fly within the block.The most demanding matrix products,
Q·KᵀandP·V, now also run at maximum speed via hardware__dp4a.A critical point for Pascal: honest
FP32online softmax. The intermediate exponential calculation (softmax) between two multiplications is performed strictly in 32-bit precision (FP32). We deliberately avoided using anyhalf2(FP16) instructions there to prevent accidentally incurring the same 64x speed penalty on GTX 1000 cards. Additionally, the kernel includes full support for GQA (Grouped-Query Attention) and attention masks.
The results exceeded expectations: the `FLASH_ATTN_EXT` operator itself sped up by 2.12x! Total sampling time on the `anima-Q4_K` model dropped to just `28.66 s` (1.40 s/it, a +71.8% improvement over stock). And for the `anima-Q3_K` version, we saw a time reduction from `52.49 s` to `28.46 s` (1.39 s/it) — an impressive +84.4% speed increase!
Step 3. Two-level memory operation: Persistent W8 Cache + Scratchpad Buffer
While everything ran flawlessly on the relatively compact Anima model, we painfully hit the VRAM ceiling on an 8GB GTX 1070 as soon as we moved to truly heavy modern giants like `Krea 2` (~5.3 GB) and `Z-Image` (~5 GB).
Why did this happen? Here's why: to operate without delays, our core from Step 1 needs to store an unpacked `int8-copy of the weights in VRAM. For a small model, this isn't an issue. However, when the model itself takes up over 5 GB, attempting to store its unpacked cache alongside it either leads to an immediate Out of Memory crash or, even worse, the `ggml_graph_cut` internal scheduler detects a VRAM deficit, starts slicing the computation graph into dozens of small pieces, and shuffles layers back and forth over the slow PCIe bus at every step.
We needed an elegant engineering solution that would let us have our cake and eat it too: maintaining the speed of `128×128` tiles while fitting within the 8GB limit. This led to the creation of a two-level memory scheme in `dp4a_gemm.cu`, paired with new ultra-fast unpacking kernels (`32×8`, 8 warps per block):
Level 1 (
Persistent W8 Cache- persistent cache in VRAM). The kernel caches unpacked `int8` layer weights in VRAM as long as a robust safe reserve of `1536 MB` of free memory remains on the card (a `cudaMemGetInfo < need_bytes + 1536 MB` check automatically stops further cache growth). Why 1.5 gigabytes? This reserve is guaranteed to be enough for the graph's working buffers and the VAE decoder, ensuring that `ggml` never slices the model into segments.Level 2 (
On-the-fly Layer Scratchpad- temporary single-layer buffer). All layers of a heavy model that didn't fit into Level 1 (or all layers, if `SD_CUDA_DP4A_CACHE_MB=0` is forcibly set) are not rolled back to the slow stock `mmq`! Instead, immediately before matrix multiplication, the current layer is unpacked in microseconds into a single, reusable temporary buffer, sized only ~16–96 MB (Scratchpad), and is still processed by our fast `128×128 __dp4a` kernel.
Battle test: When we completely disabled the persistent cache (`CACHE_MB=0`) for the experiment, leaving only a tiny 16MB Scratchpad, the `anima-Q4_K` model yielded `29.36 s` (1.43 s/it) compared to `28.66 s` with the full cache. The speed loss was a negligible 2%, but the VRAM savings were colossal! Crucially, the 5.5GB `Krea 2 Turbo Q3_K` now comfortably fit into the GTX 1070's 8GB of memory and accelerated from a stock `50.17 s` (6.03 s/it`) to `28.59–28.67 s` (3.25–3.32 s/it), delivering a clear +75% boost!
Step 4. Supporting the entire zoo of quants and the `sd-server` mystery
To make our backend a versatile tool, rather than just a crutch for one specific file, Hydra and I developed fast 32x8 decompression kernels for the entire lineup of popular ggml quantization formats:Q3_K, Q4_K, Q4_0, Q4_1, Q5_K, Q5_0, Q5_1, Q6_K, and Q8_0. (A quick note for the curious: the Q6_1 format simply doesn't exist in ggml; 6-bit weights are exclusively represented by Q6_K blocks. We also intentionally omitted the specific family of IQ* vector quants.)
However, when it came time to integrate our solution into sd-server for use within my local CoT Studio, a very insidious bug surfaced. I tried generating a heavy Z-Image (Q5_K) model at 832x1216 resolution through the studio and saw a horrifying 11 s/it. This was pure stock speed! How could this be, when everything flew in the console-based sd-cli?
A quick investigation revealed a classic build system trap: the SD_USE_CUDA compilation flag in CMakeLists.txt was only being passed to the console client. The sd-server target was built without it, silently ignoring our backend. Once we fixed CMake and rebuilt sd-server_DP4a.exe, the Z-Image step time directly within the CoT Studio interface immediately plummeted from 11s to 6.9s (even with the text encoder running on the GPU). In pure CLI mode, it dropped even further, all the way to 5.43 s/it!
Step 5. Server cache isolation and protecting VAE from the FP16 1:64 trap
In the final polishing stage, we addressed two more critically important engineering issues, without which the backend couldn't be considered stable:
Safely clearing the cache when changing models in
sd-server(g_state[device]). What's the catch here? The `sd-cli` console application launches, generates an image, and then exits, so the operating system automatically reclaims all its memory. However, `sd-server` runs continuously in the background. Our L1 cache stores unpacked weights based on the tensor's video memory address (src0->data). If you unload, say, an Anima model in the server and then load Krea 2 in its place, the NVIDIA driver might allocate the same freed VRAM addresses to the new model. Without explicitly clearing the cache, the kernel would see familiar addresses and feed the new model the old weights from the previous one! That's why we've separated the cache state for each graphics card in the system (g_state[device]) and strictly tied its clearing (ggml_cuda_dp4a_clear_cache()) to the model context's release (free_sd_ctx), without affecting incremental `--offload-to-cpu` unloading.Preventing
cuBLASperformance drops in VAE. Since the VAE decoder and certain auxiliary layers are often stored in `FP16` format, there was a risk that NVIDIA's standard `cuBLAS` library on Pascal cards would try to compute them in native 16-bit mode, incurring the notorious `1:64` speed penalty. To close this loophole, we explicitly enabled `FP32` accumulation mode (prefer_f32_output = true/CUDA_R_32F) in the `ggml-cuda.cu` file for all `GGML_TYPE_F16` operations on SM 6.1 architecture when `--dp4a` is active.
GTX 1070 8GB test results: numbers, quality, and stress test
Theory and code are great, but let's see how this entire architecture performs in real-world tasks on our test subject, the GTX 1070 8GB.
Basic performance measurements (512×768, VAE tiling 512×512, encoder on CPU)
First, we ran a series of tests in the classic vertical `512×768` format. This helped us evaluate not only the maximum boost with a full cache but also how fast our second memory level (the temporary Scratchpad buffer with `CACHE_MB=0` explicitly disabled) operates:
Model family and quantization | Operation mode | Step speed | Total sampling time | Acceleration |
Anima (Q4_K), 20 steps | Stock ( |
|
| — |
Anima (Q4_K), 20 steps |
|
|
| +71.8% |
Anima (Q4_K), 20 steps |
|
|
| +67.7% |
Anima (Q3_K), 20 steps | Stock ( |
|
| — |
Anima (Q3_K), 20 steps |
|
|
| +84.4% |
Anima (Q3_K), 20 steps |
|
|
| +70.7% |
Krea 2 (Q3_K), 8 steps | Stock ( |
|
| — |
Krea 2 (Q3_K), 8 steps |
|
|
| +75.0%…+75.5% |
Here's an interesting technical nuance: in stock mode, the lower Q3_K quantization on the Anima model actually performs slower than Q4_K (2.62 с/it versus 2.41 с/it). This is because the stock kernel struggles to parse odd 3-bit format bitmasks at each step. However, in our --dp4a mode with caching, both formats are unpacked into flat int8 only once. As a result, both Q3_K and Q4_K deliver identical 1.39–1.40 с/it performance, and the boost for Q3_K over stock reaches 84.4%!
We also tested a demanding Z-Image (Q5_K) at a high portrait resolution of 832×1216 (2 steps, --cfg-scale 1.0):
Operation Mode | Step 1 (with initialization) | Step 2 (steady state) | Total Sampling (2 steps) | Speedup |
Stock (without |
|
|
| — |
Our build ( |
|
|
| +78.1% |
In the steady second step, we see nearly a twofold reduction in waiting time — from 10.24 с down to 5.43 с.
Quality and speed test at 768×768 (8 steps, --seed 42)
Any enthusiast's main concern when they hear about moving activations and attention to INT8 is, 'Will the image turn into a blurry mess with artifacts?' To answer this definitively, we benchmarked all three model families at 768×768 resolution (8 steps, --cfg-scale 1.0, fixed --seed 42) and directly compared the renders:
Model family | Sampling (stock) | Sampling (--dp4a) | Total time (stock → --dp4a) | Visual verdict |
Krea 2 (Q3_K) |
|
|
| Identical results: skin pores, eye glint, eyelashes, brass gears, and film grain are all perfectly clear, with no blurring whatsoever. |
Z-Image (Q5_K) |
|
|
| Identical results: skin texture, individual hairs, reflections, and metallic surfaces are absolutely pristine. |
Anima (Q4_K + Turbo LoRA) |
|
|
| Sharp lines, contrast, and fine details show no degradation whatsoever. |
Stress test in true FullHD (1920×1080) and VRAM monitoring
But can our two-tier memory scheme withstand a true stress test? We ran a generation at full FullHD (1920×1080) using the demanding Krea 2 (Q3_K) model on the same 8GB GTX 1070, while simultaneously monitoring VRAM consumption via nvidia-smi every half-second:
Metric | Stock (without --dp4a) | Our Build (--dp4a) | Summary |
Step 1 |
|
| 1.78x faster |
Step 2 (stable) |
|
| 2.02x faster |
Net sampling (2 steps) |
|
| 1.88x faster |
VAE decoding (18 |
|
| Full parity |
Total generation time |
|
| Nearly 49 seconds saved |
Peak VRAM consumption ( |
|
| Only +122 MiB (headroom ~ |
Average VRAM consumption |
|
| +467 MiB |
Look at these figures: in a heavy FullHD workload, we saw exactly a twofold acceleration. The time dropped from 48.69 seconds to just 24.13 seconds, a 2.02x speedup! Meanwhile, peak VRAM consumption only rose by a modest 122 megabytes, leaving over 1.3 GB of free space. Our 1536 MB limiter and Scratchpad buffer worked like a charm.
Finally, we tested an even heavier version of Krea 2 in the Q4_K quant (the file itself weighing — 6.72 GB) with --offload-to-cpu enabled, all on the same 8 GB GTX 1070:
At a
512×512resolution, the sustained step accelerated from4.03 s/itto2.52 s/it(1.60x), and overall sampling time decreased from15.15 secondsto12.35 seconds.In a heavy
1024×1024square, step speed increased from18.34 s/itto10.09 s/it(1.82x), reducing sampling time from44.47 secondsto27.09 seconds.
Now for the most interesting part: generation examples and a comparison of the stock kernel against our custom one. We want to re-emphasize that checkpoints and seeds remained identical across all test runs and for both kernels:
Anima (Q4_K + Turbo LoRA)
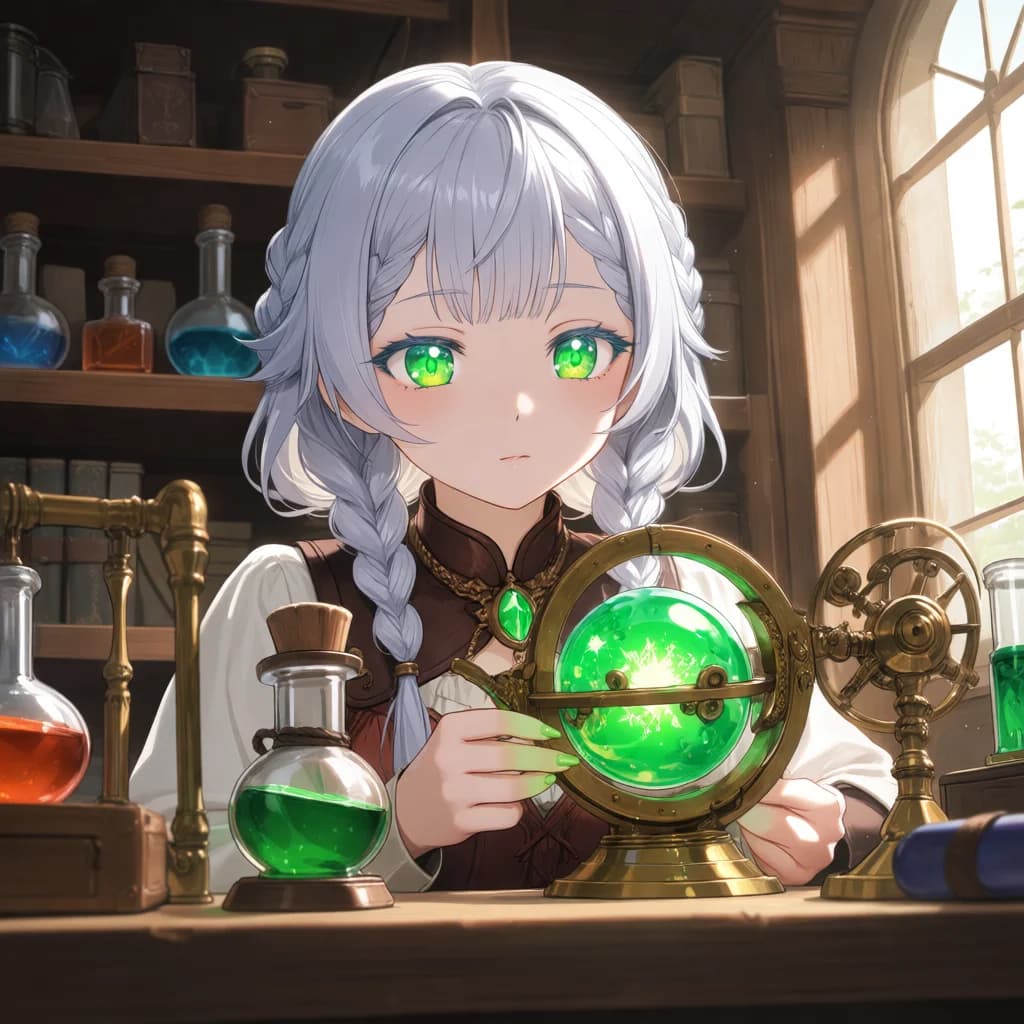
 DP4a (INT8)
Z-Image (Q5_K)
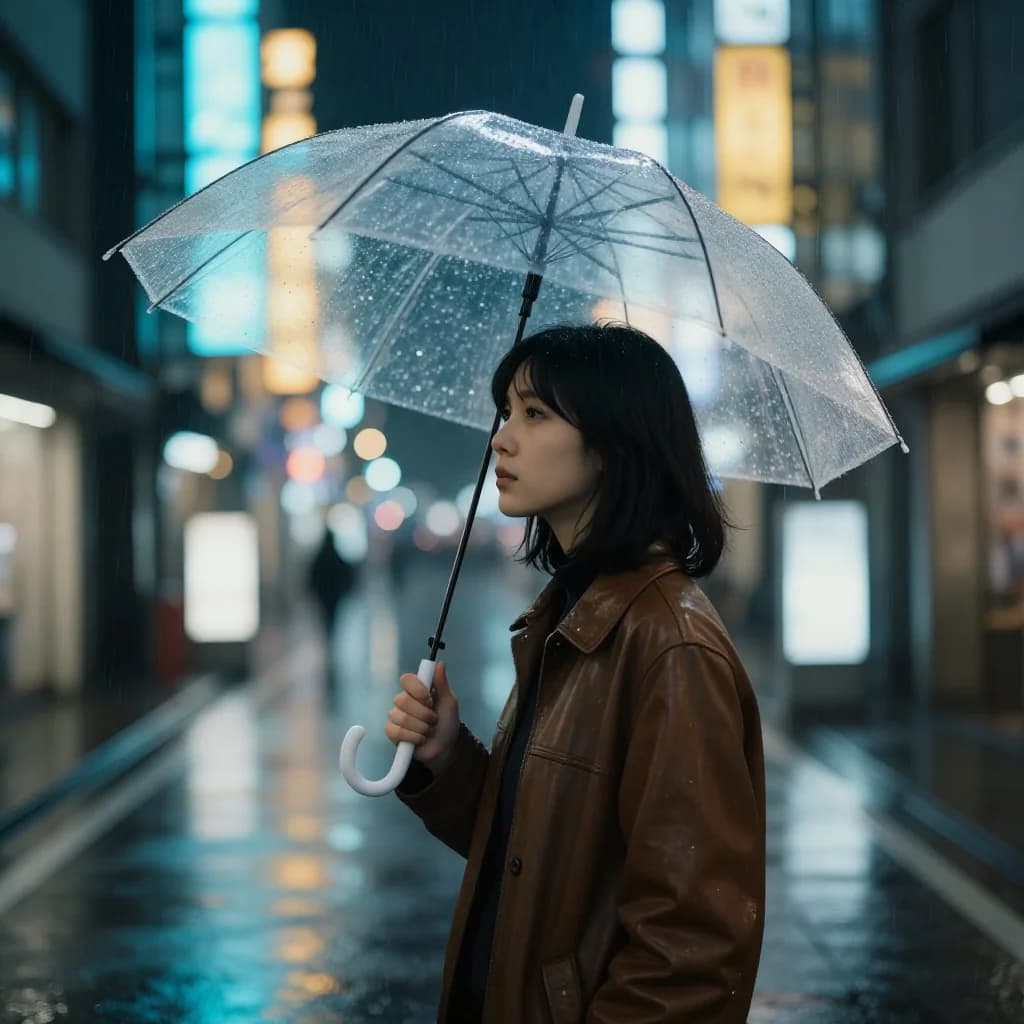
 DP4a (INT8)
Krea 2 Turbo (Q3_K)
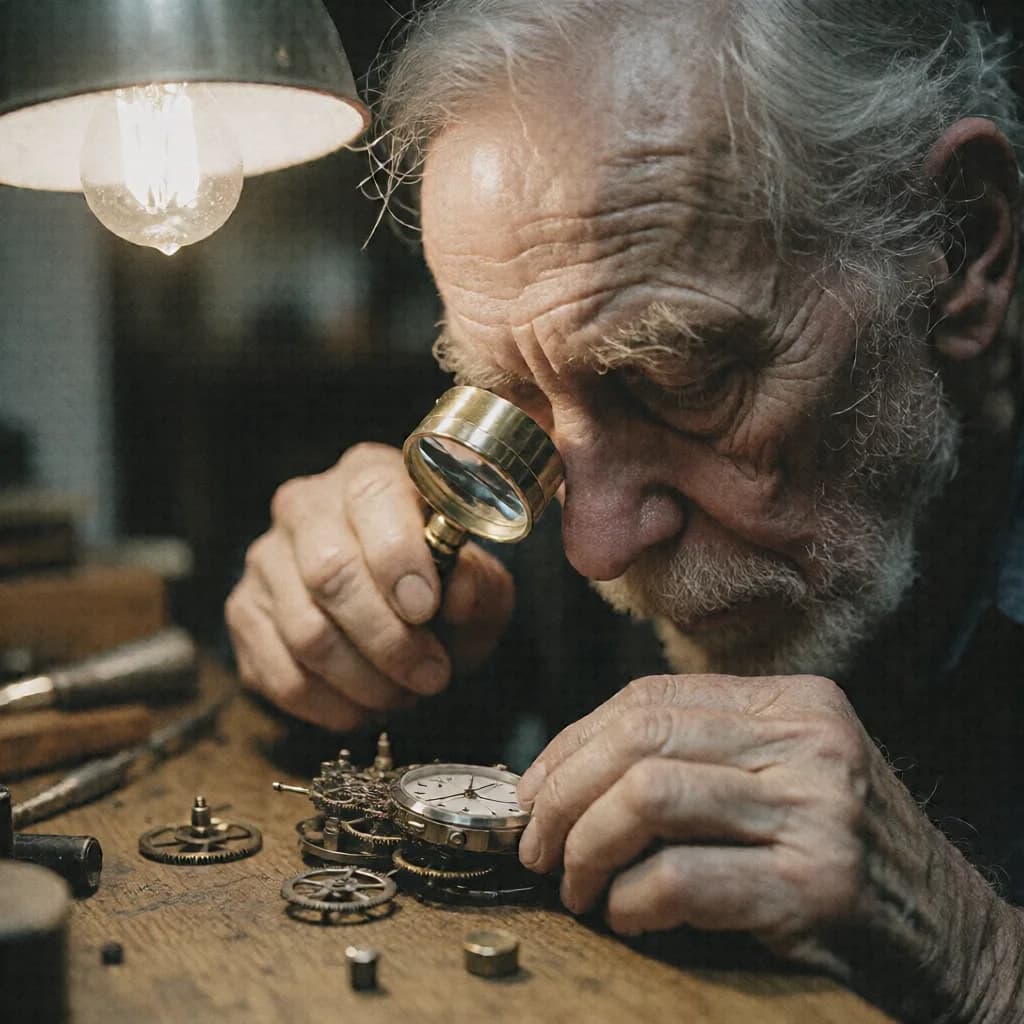
 DP4a (INT8)
The only thing noticeable when directly overlaying the images is a slight shift in the placement of minor details, such as small gears in the background or finger positions. This is an absolutely normal consequence of changing the rounding order during on-the-fly INT8 activation quantization; however, the sharpness, detail, and lighting remain identical to the stock version.
Limitations and pitfalls
I wouldn't be doing my job as an author if I just showed you pretty acceleration graphs and stayed silent about the nuances. Any low-level optimization has its physical and architectural limits. During our tests, Hydra and I encountered three critical points you should know about upfront:
1. Raw .safetensors in FP16 / BF16 format don't directly accelerate linear layers
Our matrix kernel W8A8 __dp4a exclusively processes quantized weight formats (Q3_K – Q8_0). If you feed the program an original, unquantized checkpoint in BF16 or FP16, our backend will only accelerate FlashAttention blocks (which offers a modest +15–20% boost), while all primary matrix multiplications will still go through the standard cuBLAS path.
How can you bypass this without converting the model on disk? It's simple: just pass the flag --type q8_0 when launching .safetensors. In this scenario, stable-diffusion.cpp quantizes the weights into the 8-bit Q8_0 format on the fly during loading. The model immediately occupies half the VRAM, retains ~99% of the original visual quality, and fully activates our __dp4a acceleration.
2. The --offload-to-cpu and ggml_graph_cut trap: a revealing case study on the P102-100 (10 GB)
A very instructive story emerged when we moved our tests to our 'headless' mining accelerator, the P102-100 10 GB. The heavy Krea 2 model in Q3_K quantization (~5.3 GB) performed exceptionally well on the P102 (~200 seconds for a demanding run). However, when we tried running the same model with larger Q4_K and Q4_0 quantizations (file sizes of 6.7–7.0 GB), generation time suddenly plummeted to ~450 seconds — almost back to stock performance!
And here's the kicker: on an 8GB gaming GTX 1070, that same 6.72 GB Q4_K file just demonstrated an honest 1.82x acceleration (10.09 s/it vs. 18.34 s/it). What the hell was going on?
The key lies in how the --offload-to-cpu flag interacts with the ggml_graph_cut scheduler. As soon as the combined total of 'model weights + graph work buffers' (which on the P102 took 8.7 GB out of 10 GB) crosses the internal threshold for a single contiguous segment, ggml_graph_cut forcibly slices the model into ~33 smaller segments, each containing 13 tensors. In the logs, this manifests as endless 'loading tensors completed, taking 0.21s' lines, dozens of times with each sampling step! Essentially, the engine constantly shuffles weight chunks between system RAM and VRAM via the PCIe bus, right in the middle of computations.
On a full-fledged GTX 1070 with its wide PCIe 3.0 x16 bus, these transfers happen relatively painlessly. However, on the mining-specific P102-100, where the bus is physically throttled to PCIe 1.0 x4, the bottleneck from shuttling gigabytes of data back and forth completely negates any performance gains from the fast GPU core.
The conclusion is simple: if you're using P100 series mining cards with a slow PCIe bus and the --offload-to-cpu flag, it's critical to choose a model quantization that fits into a single contiguous segment without graph splitting (for 12-billion parameter models like Krea 2 on a 10 GB card, the ideal balance is Q3_K, weighing in at ~5.3–5.5 GB).
3. Where else does this architecture work beyond stable-diffusion.cpp? (Spoiler: we've already implanted it into 3D auto-rigging!)
The combination of our pipeline W8A8 __dp4a, honest FP32 softmax in FlashAttention, and blocking slow FP16 1:64 in cuBLAS isn't some specific hack solely for image generation. Instead, it's a universal recipe for the Pascal architecture (SM 6.1), delivering exponential gains wherever the graphics card is compute-bound (compute-bound), which means it's multiplying sufficiently 'wide' matrices with a data stream dimension of M >= 16.
To avoid merely speculating that this approach could accelerate video or audio generation, or the prefill phase of long prompts in LLMs, Hydra and I took things further and literally implanted our dp4a_gemm and fattn_dp4a kernels into a completely different project: a 3D skeleton and skinning generator for game models (SkinTokens / skt_rig).
To verify this, we quantized the base model skintokens from FP32 to Q8_0 format. (The file size on disk immediately shrank from 2075 MB to 1354.7 MB.) We then ran a full skeleton generation cycle on a test 3D model (woman.sktmesh, beam = 10, --seed 42). The results of this test are a perfect illustration of how GPU physics work:
Operating mode (skt_rig) | shape | cond | backbone (beam = 10) | fsq_decoder (J = 52) | Total time | Peak VRAM |
FP32 (reference stock) |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
Here's how consistently different parts of a single neural network behave:
Where the chip handles complex math (the
fsq_decoder, with a matrix dimension ofM = 8192), we saw a precise 2.01x speedup, or 101% faster performance! The decoder's runtime plummeted from14.93 sto7.42 s, all while still producing the exact same 52-bone skeleton output. As an added bonus, enablingfattn_dp4ainFsqDecoderyielded memory savings: the core no longer has to allocate an intermediatekqattention buffer, which further lightens the load on VRAM.In the autoregression (
backbone) block, however, we saw only minimal gains, with the runtime dropping from13.49 sto12.27 s. Why the small improvement? This is because withbeam = 10, the batch size isM = 10, which falls below theM >= 16threshold needed for efficient tile utilization. During token-by-token decoding, the graphics card simply waits for the memory controller to transfer weights from the GDDR5 chips (mmvq) while the CPU handles its operations. This means the task is purely memory-bound, bottlenecked by memory bandwidth rather than the chip's ALU.
That's why it's crucial to understand the technology's limitations. For token-by-token text generation in large language models (batch = 1, M = 1) or in narrow autoregressive tasks, W8A8 won't perform miracles; video memory speed is the sole determinant of performance there. But as soon as there's a dense data stream — like with diffusion, 3D decoders, audio/video encoding, or batched prefill for large LLM contexts — our native __dp4a pipeline unleashes 200% of the potential from older GTX 1000 and P100 series cards!
Summary
Was it worth spending dozens of hours on low-level optimization for an architecture that will be a decade old by 2026? In my opinion, absolutely yes. This isn't just about our test GTX 1070 8 GB or the mining P104-100 and P102-100 cards.
Let's take a broader look. What exactly is the Pascal architecture with an SM 6.1 index? It encompasses a vast array of cards still widely used in home PCs, workstations, and budget AI servers. Beyond the mass-market GTX 1060 6 GB, GTX 1070 Ti, and GTX 1080, it also includes true heavy hitters built on the full or near-full GP102 die:
The legendary GTX 1080 Ti (11 GB) and its older siblings, the TITAN X (Pascal) and TITAN Xp (12 GB), are still going strong. With 11–12 gigabytes of fast GDDR5X memory and a wide 352/384-bit bus, our
W8A8 __dp4apipeline can handle quantizedQ4_KandQ5_Kcheckpoints from modern diffusion giants without any graph splitting. These cards offer a staggering ~44–48 TOPS of integer performance.Local AI enthusiasts love the server-grade NVIDIA Tesla P40 (24 GB), as well as the professional Quadro P6000 (24 GB). For these two beasts, our new core offers a literal second life. Why? With 24 GB of VRAM, you can completely forget about video memory limits. Any demanding model, such as Krea 2, Z-Image, or Flux, not only fits entirely into the card's memory but also fully accommodates our Persistent W8 Cache (Level 1). That means no PCIe transfers, no compromises—just a pure
128×128 __dp4apipeline running on all 3840 CUDA cores of the GP102 chip.
Essentially, when software stops mindlessly struggling with a crippled FP16 (1:64) and fully utilizes hardware INT8 __dp4a with proper memory management, the good old Pascal cards transform from slow underperformers into truly capable computing machines. They can generate images almost twice as fast as stock, with no loss in visual quality.
Let me also explain how this project came to life. For me, it was a prime example of healthy engineering synergy between humans and AI. Initially, working with the smaller Gemini 3.8 Flash, we had to literally fight for every hypothesis and correct childish typos in the code. However, switching to Gemini 4 Hydrogen (our Hydra) was a game-changer. When you have a clear understanding of the hardware's physics, can identify where memory or the PCIe bus chokes, and set a precise architectural task, a tool like Hydra allows you to implement such low-level C++/CUDA features. Achieving this alone would take a single developer months of sleepless nights digging through NVIDIA's documentation.
We are openly sharing all our developments: the source code for the dp4a_gemm.cu and fattn_dp4a.cuh kernels, ready-made patches for the upstream stable-diffusion.cpp project, and pre-compiled Windows binaries (sd-cli_DP4a.exe and sd-server_DP4a.exe) in public access. Grab them, run them on your GTX 1070, 1080 Ti, P104, P102, Tesla P40, or Quadro P6000, integrate them into your own projects, and be sure to share your benchmark results in the comments.
Well, I've given you some food for thought (and code for testing); now I need to get back to the test bench. As you might have guessed from the spoilers in this article, one of our upcoming pieces will feature an in-depth breakdown of a top-tier mining accelerator based on the GP102 chip—the very same P102-100 10GB. So, stay tuned!
Repository link: sd-cpp-pascal-dp4a